
Most large cloud migrations do not fail. They stall. The application is on the cloud, the migration program has been declared done, and nothing about the application has changed: features take as long as they did, the bill is higher than the business case said, and the AI coding tools every other team is using cannot safely touch it. The lift succeeded and the shift never happened.
This post is about the choice that produces that outcome, and how to make it differently.
The three options, honestly described
Rehost (lift and shift) moves the application to cloud infrastructure with no code changes. It is fast, low-risk, and a legitimate first step. What it does not do is change the application. A monolith on a VM in the cloud is still a monolith: it scales as one unit or not at all, so elasticity buys nothing, and it often costs more than it did on premises because the cloud bill is sized for the peak.
Replatform (lift, tinker, and shift) makes minimal changes to run on a managed platform: a managed database instead of a self-run one, a container instead of a VM, a managed queue instead of an installed broker. Low risk, real operational savings, and it needs people who know both the existing application and the target platform. It still leaves the architecture alone.
Refactor changes the internal structure while preserving external behavior (the fuller refactor, rearchitect, or rewrite decision is its own post). For a large existing application this means separating domains, removing dead code, resolving shared classes, and making the pieces independently deployable. It is the option that changes what the application can do on the cloud and how fast your team can change it. It is also the option organizations have historically avoided, for the sound reason that nobody could scope it or prove it would not break production.
A fourth option, encapsulate, wraps the existing application in APIs so other systems can use it without touching it. It is useful for buying time and it changes nothing underneath. Retire, replace, and rebuild complete the familiar list of seven; they are business decisions more than engineering ones.
Why migrations stall at lift-and-shift
The stall has a consistent shape.
The application was never designed for the cloud, so moving it there does not unlock the cloud’s properties. Elastic scaling requires components that can scale independently; a monolith has one. Managed services require boundaries at which to plug them in; a monolith has few. Fast deployment requires small, testable units of change; a monolith has one unit and a full regression suite.
The bill arrives higher than expected because a monolith reserves capacity for its peak all the time. The feature backlog does not move because the code that made features slow on premises is the same code. And the migration becomes a can kicked down the road: “we will modernize after we migrate” turns into a second program that never gets funded, because the first one was declared a success.
The barrier is people rather than technology: nobody can say what the application does well enough to change it safely, so nobody does.
How to choose
Five criteria, applied per application rather than per estate.
Business value. Is this application where the business needs to move faster, or where it needs to stop spending? Value drives refactoring; cost alone usually justifies only rehosting.
Complexity. Past roughly 500,000 lines of code or 1,000 classes, an application will not modernize itself as a side effect of migration, and it is also the application where the payoff from refactoring is largest.
Cost over time. Compare the run cost of a rehosted monolith (peak-sized, licensed, unchanged) against the project cost of refactoring plus the run cost of the result. The rehost number is a cost forever; the refactor number is a cost once.
Security posture. Frameworks out of support and dependencies that cannot be upgraded because “we do not know what will break” are a reason to refactor, not to rehost the risk to a new address.
Risk of moving versus risk of staying. Historically this favored rehosting because refactoring risk was unbounded. It no longer is, for the reason in the next section.
Then iterate. The right answer for one domain of the application may be different from the right answer for another, and the decision should be revisited as each domain lands.
Realistic timelines
Migration duration is driven by the number and complexity of monoliths more than by data volume or bandwidth. Plan three phases: strategy and business case, discovery and evaluation of each application against the criteria above, and the migration itself. Within the migration, sequence refactoring the way the strangler fig pattern does: decouple business logic first, extract services, move front ends, and migrate the database layer last.
What changed the refactor calculation
The reason refactoring was the option everyone admired and nobody chose was labor and risk: understanding a large existing application well enough to restructure it, writing the restructured code, and proving it still worked.
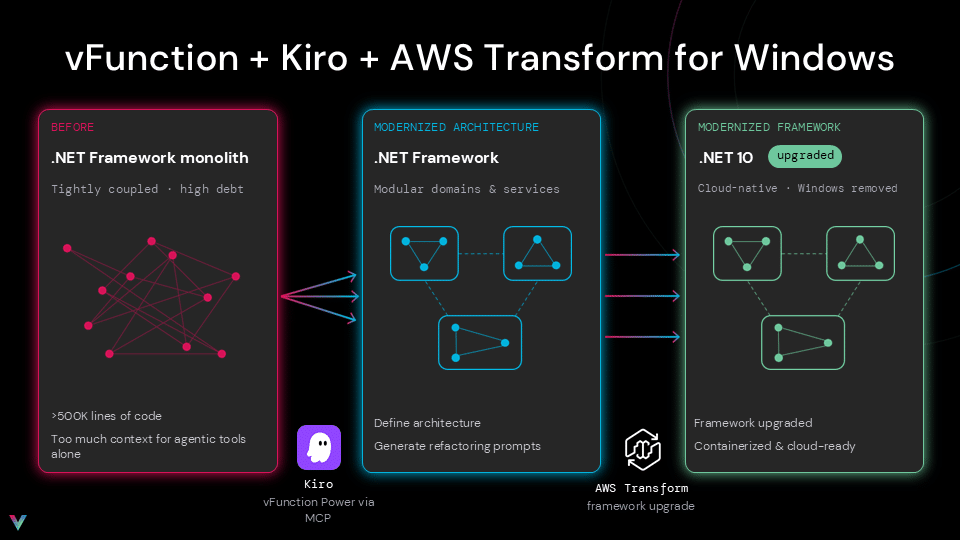
AI coding tools such as Kiro, Claude Code, AWS Transform, and others have removed the constraint on the writing. What they need to work on a large existing application is what the migration team always needed and never had: an accurate picture of how the application runs in production, a target architecture to work toward, a specification for each domain, and tests that prove the new code behaves like the old. Those can now be produced from the running application. That turns refactoring from a bet into a sequence of tested changes, which is what makes it a choice a migration program can actually make.
Where vFunction fits
vFunction is a modernization platform for large existing Java and .NET applications. Using runtime analysis and proprietary data science, it captures how the application actually runs in production and helps your architects define a target architecture before modernization begins. It generates a specification for each domain from the observed runtime flows and integration tests from the same data. Kiro, Claude Code, and other AI coding tools receive them through vFunction’s MCP server and downloadable skills and refactor the application one domain at a time under your team’s review; AWS Transform is used within the same workflow for .NET and Java upgrades. vFunction’s engineers run the process with your team until your team can run it alone. For an application on AWS or moving to AWS, AWS funds the vFunction work through its ISV tooling program.
Keep learning: Most AWS migrations stall because applications are too complex · How to conduct an application assessment for cloud migration