The request usually arrives as a deadline: the 8-million-line Java application on a fleet of VMs, or the .NET Framework system on Windows Server, needs to be on EKS or ECS by next year. The platform team can put a monolith in a container in an afternoon. What happens after that is the subject of this post.
Containers and Kubernetes deliver real, tactical benefits to any application: repeatable packaging, automated rollout and rollback, process-level isolation, managed patching of the host. They deliver strategic benefits (independent scaling, fast deployment, lower run cost) only to applications structured to receive them. A large monolith is not, and putting it in a container does not change that.
What breaks when you containerize a monolith as-is
It still scales as one unit. Autoscaling works by adding replicas of a small thing. A replica of a monolith is a whole monolith. You pay for the peak of the busiest component in every copy.
State is in the wrong places. In-memory sessions, local file writes, singletons that assume one process, scheduled jobs that assume one host: all of it breaks when pods are ephemeral and can be rescheduled at any moment.
Startup defeats the platform. A monolith that takes many minutes to start and needs a large heap fails liveness probes, blocks rolling updates, and bin-packs badly. The orchestrator’s strengths become its failure modes.
Configuration is hard-wired. Environment-specific values baked into the build or read from files on a known path do not survive the move to config maps and secrets without changes to the code.
You acquire a second debt pile. Logging, secrets, resource limits, persistence, network policy: a container platform needs each of these managed, and a monolith gives you one enormous workload to manage them for. The old observation that a container strategy without an application strategy produces “technical debt greater than legacy code” has held up.
The migration then stalls: the application is in a container, on the cloud, unchanged, and the business case (cost down, delivery up) does not arrive. Containerization is the starting point, not the finish line (the fuller rehost, replatform, or refactor decision is its own post).
What has to change in the application
Four things, in roughly this order.
Externalize state and configuration. Sessions to a store, files to object storage, configuration to the environment, scheduled work to something that tolerates more than one instance. This is the twelve-factor list, and it is prerequisite work whether or not you go further.
Make startup fast enough to be scheduled. Lazy initialization, smaller units, or (the real fix) less code per deployable unit.
Find the domain boundaries in the running application. Which classes, resources, and tables are used exclusively by one part of the system, and which are shared. This is measured from production behavior, not guessed from package names. It tells you what can be carved out cleanly and what has to be untangled first.
Extract the domains that pay. Highest exclusivity and highest rate of change first. Each extracted domain becomes a small, fast-starting, independently scalable service that the container platform can actually help. The monolith shrinks behind a routing layer. New functionality goes in the extracted services, not back into the core.
Sequencing it
- Inventory from runtime. Observe how the application actually runs. Establish the domain map, the exclusivity data, the dead code and dead flows, and the shared classes.
- Containerize the monolith as a baseline, not a goal. Get it running in a container with externalized state and config so the deployment pipeline exists. Do not declare victory.
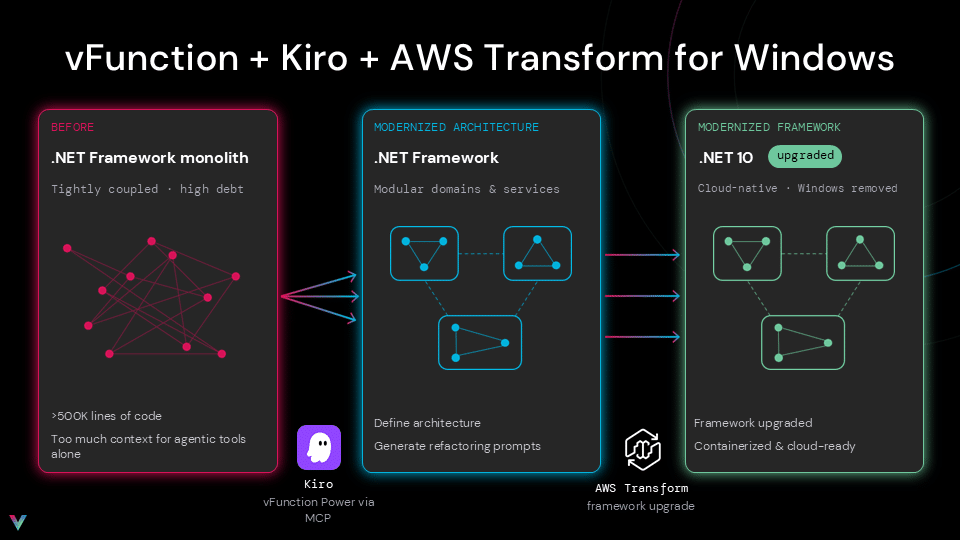
- Define the target architecture. Your architects decide which domains become services, which stay in the core, and what the boundaries are. Do this before the first extraction.
- Extract one domain at a time behind a façade (the strangler fig pattern). Specification derived from the monolith’s real behavior; integration tests that prove the new service matches the old; traffic routed to the new service with automatic rollback. Land it on ECS, EKS, or a serverless runtime as fits.
- Upgrade the stack as domains land. A .NET Framework domain becoming a .NET 10 service (full-stack Windows modernization), a Java EE domain moving to a modern runtime, a stored procedure becoming application code. Each is tractable once the domain is small and specified.
- Repeat, keeping the monolith shrinking.
What this needs from AI coding tools, and what they need from you
Steps 4 and 5 are writing, and AI coding tools such as Kiro, Claude Code, AWS Transform, and others now do that writing well when given a bounded, specified domain. Steps 1 and 3 are the part they cannot do from the code alone on an application past roughly 500,000 lines of code or 1,000 classes: the system does not fit in a context window, and static analysis shows every dependency with no signal about which ones production actually exercises. Give the tools the runtime picture, the target architecture, the specification, and the tests, and the VM-to-container migration becomes a series of tested changes. Skip that, and you get a distributed monolith on Kubernetes, which is the same stall with more moving parts.
Where vFunction fits
vFunction helps teams move complex Java and .NET applications from VMs to containers by giving AI coding tools the context they need to modernize large existing applications. Using runtime analysis and proprietary data science, it captures how the application actually runs in production, measures exclusivity, surfaces dead code and shared classes, and helps your architects define the target architecture before the first extraction. It generates a specification for each domain from the observed runtime flows and integration tests from the same data. Kiro, Claude Code, and other AI coding tools receive them through vFunction’s MCP server and downloadable skills and extract or rewrite the domain under your team’s review; AWS Transform is used within the same workflow for .NET and Java upgrades. vFunction’s engineers run the process with your team until your team can run it alone. For an application on AWS or moving to AWS, AWS funds the vFunction work through its ISV tooling program.
Keep learning: Modernize Large VM Apps to Containers · Beyond EC2: a practical guide to moving to AWS-native services